www.industryemea.com
05
'26
Written on Modified on
Avalue Launches Distributed AI Computing Infrastructure
Avalue expands its hardware portfolio to deliver scalable AI solutions across data center and industrial edge applications.
www.avalue.com
As artificial intelligence integration expands across industrial automation, smart healthcare, machine vision, retail, and public services, enterprises are shifting from strictly centralized artificial intelligence processing toward highly distributed computing architectures. AI training, real-time inference, high-speed data acquisition, and human-machine interaction require distinct levels of computational performance, power efficiency, hardware scalability, and operational reliability. To address these varied engineering requirements, Avalue Technology Inc. has introduced a comprehensive hardware portfolio that spans data center infrastructure, specialized edge AI systems, embedded platforms, and intelligent user endpoints. This deployment strategy allows system integrators to allocate specific AI workloads to the most appropriate computing layer within a network.
High-performance centralized computing infrastructure
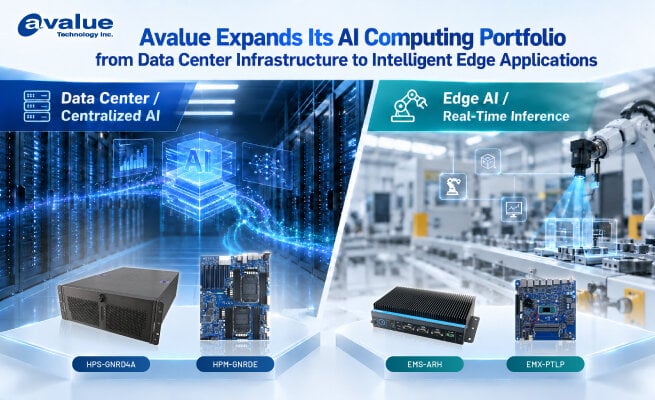
At the enterprise and data center tier, Avalue provides high-density server platforms designed for compute-intensive workloads, large-scale data processing, and complex AI model training. The HPM-GNRDE EATX server motherboard and the HPS-GNRD4A 4U tower system feature dual Intel Xeon 6 processors. These systems utilize high-capacity DDR5 memory modules and PCIe Gen5 expansion interfaces to support multi-GPU configurations. Equipped with flexible storage options, advanced networking interfaces, and remote management tools, these platforms deliver the raw computational power and hardware scalability essential for processing medical imaging analysis and centralized industrial data management.
Real-time edge inference systems
Many modern AI applications require immediate decision-making capabilities at the physical location where data is generated. Processing data at the network edge significantly reduces latency, network traffic congestion, and bandwidth consumption for applications like autonomous mobile robots, equipment monitoring, and AI-assisted healthcare. To support these deployments, Avalue introduced the fanless EMS-ARH system, powered by Intel Core Ultra processors. By integrating CPU, Intel Arc GPU, and Neural Processing Unit computational resources, the system delivers up to 99 TOPS of artificial intelligence performance. Designed for harsh operating environments, the unit supports a wide operating temperature range, accepts 9V to 36V DC power input, and provides modular input and output expansion capabilities.
Embedded platforms and intelligent endpoints
For customized system development, the ECM-PTL 3.5-inch micro module and EMX-PTLP Thin Mini-ITX motherboard extend heterogeneous computing capabilities to embedded architectures. Featuring high-speed memory support, multiple display outputs, and M.2 expansion slots, these platforms enable original equipment manufacturers to develop highly specific, scalable edge AI solutions. At the endpoint tier, Avalue’s medical and industrial Panel PCs merge data acquisition, real-time inference, and visualization to support human-machine interaction in self-service terminals and clinical diagnostic systems. These endpoints connect field operators with centralized management platforms to optimize operational response times.
Additional Context: Latency and processing decentralization
The structural shift toward distributed AI architectures directly addresses the physical limitations of cloud computing in time-critical industrial environments. Backhauling massive volumes of uncompressed machine vision data or sensor telemetry to a central data center introduces unacceptable round-trip latency for safety-critical applications. By deploying high-performance inference nodes like the EMS-ARH directly on the factory floor, operators can filter data locally, executing rapid control decisions without relying on persistent external network connectivity. This hierarchical topology reserves the centralized dual-processor Xeon architectures strictly for asynchronous tasks, such as deep learning model training, historical data analytics, and fleet-wide predictive maintenance aggregation.
Edited by Lekshman Ramdas, InduPortals editor – adapted by AI.
www.avalue.com