www.industryemea.com
20
'26
Written on Modified on
NVIDIA Executes Record 104-Qubit Quantum Simulation on JUPITER
NVIDIA validates magic state cultivation on Europe’s JUPITER supercomputer, reducing physical qubit requirements by 90 percent for fault-tolerant architectures.
www.nvidia.com
Building utility-scale quantum computers requires overcoming physical decoherence and environmental noise that inherently degrade fragile qubit states. Because quantum logic operations introduce unavoidable gate errors, realizing practical computation demands quantum error correction architectures that synthesize stable logical qubits from large clusters of physical qubits. A critical engineering bottleneck in fault-tolerant quantum computing is the generation and purification of non-Clifford auxiliary resource states, known as magic states, which are continually consumed to perform universal quantum logic. Conventional magic state distillation circuits impose massive physical qubit and hardware overheads, consuming up to 90 percent of total quantum processor resources. Resolving these physical constraints requires high-fidelity numerical simulation across classical exascale supercomputing infrastructure to optimize fault-tolerant error architectures before committing to physical silicon fabrication.
Exascale Simulation and Magic State Cultivation
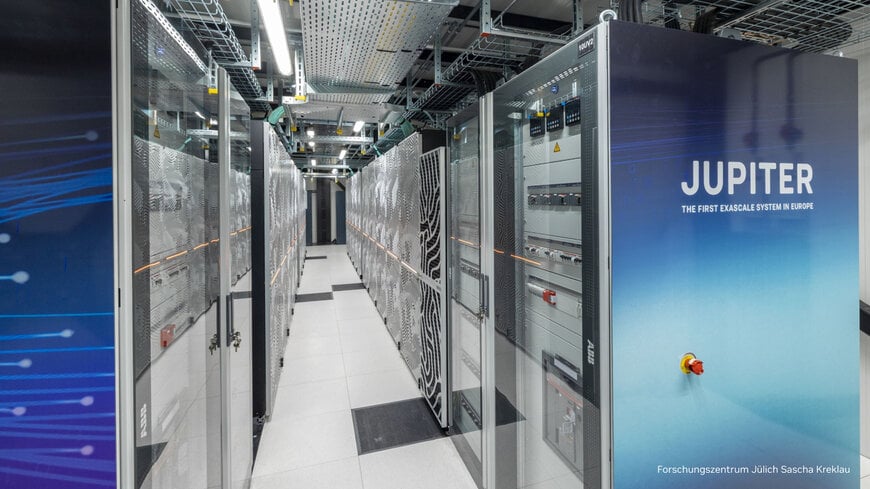
To address these resource overheads, NVIDIA, in collaboration with the Jülich Supercomputing Centre at Forschungszentrum Jülich, executed the largest comprehensive simulation of a fault-tolerant quantum processor to date on JUPITER, Europe’s first exascale supercomputer. The simulation successfully modeled a 104-qubit system subjected to realistic hardware noise, validating a magic state cultivation methodology that reduces required physical qubit counts by 90 percent compared to previous methods.
Unlike earlier baseline research at Jülich that modeled 50 qubits under idealized, noiseless conditions, this milestone evaluated magic-state cultivation under realistic environmental noise and gate infidelity. Capturing error propagation across 104 interacting qubits provides researchers with the high-fidelity data needed to forecast how physical processors execute fault-tolerant algorithms, accelerating engineering cycles for applications across molecular materials design, financial modeling, and drug discovery.
According to Jensen Huang, founder and CEO of NVIDIA, practical quantum computing demands complex fault-tolerant systems, and understanding physical behavior at scale on GPU supercomputers accelerates the realization of useful quantum applications. Kristel Michielsen, director of the Jülich Supercomputing Centre, noted that JUPITER’s exascale infrastructure provides researchers with the computational capacity to validate quantum processor designs and inform hardware decisions before fabrication.
Hierarchical Staging from Edge Clusters to Exascale Nodes
Because quantum state vector simulations experience exponential memory scaling where memory requirements double with each additional qubit, simulating a 104-qubit error-corrected system exceeds the memory envelope of conventional distributed computing clusters. To manage this computational demand, researchers deployed a staged algorithmic development pipeline.
Initial simulation models were developed, benchmarked, and debugged on an NVIDIA GB200 NVL72 rack-scale system located at the NVIDIA Accelerated Quantum Research Center (NVAQC). The facility allowed the research team to scale quantum simulation routines incrementally from four graphics processing units to several hundred nodes.
After establishing baseline convergence, the workflow transferred to the JUPITER exascale supercomputer, distributing the 104-qubit simulation workload across 8,192 NVIDIA GH200 Grace Hopper Superchips. The simulation ran using NVIDIA cuQuantum software to optimize performance and scale, coupled with the fault-tolerant logical layer of the NVIDIA CUDA-Q platform to formulate the magic-state circuit. This tiered execution architecture compressed weeks of continuous simulation runtime into several days, establishing a reproducible template for verifying large-scale quantum error-correcting codes on accelerated exascale supercomputing fabrics.
Additional Context
This section details technical specifications and competitive benchmarking not included in the original product announcement.
Universal fault-tolerant quantum computing relies on the Eastin-Knill theorem, which dictates that no quantum error-correcting code can implement a transversal, continuous universal gate set without introducing non-Clifford operations. To execute standard T-gate phase rotations necessary for universal computation, surface codes and planar lattice architectures must ingest pre-synthesized magic states. Conventional Bravyi-Kitaev magic state distillation routines ingest fifteen noisy input states to output a single purified target state, creating a footprint bottleneck where up to 90 percent of physical qubits in systems such as IBM Quantum Heron or Google Sycamore architectures would be dedicated entirely to state purification rather than algorithm execution. Magic state cultivation overcomes this overhead by adaptively entangling code patches and growing resource states directly within the fault-tolerant topological code space, bypassing multi-stage distillation factories.
In classical supercomputing benchmarks for quantum simulation, platforms such as the cuQuantum software development kit utilize tensor network contraction alongside full state vector emulators accelerated across NVLink high-bandwidth inter-GPU networks. Benchmarking against competing high-performance quantum simulation frameworks—such as Intel Quantum Simulator on x86 CPU clusters, Qiskit Aer on standard HPC nodes, or the LUMI supercomputer’s AMD ROCm-based simulations—demonstrates that simulating beyond 50 entangled qubits under non-unitary Kraus noise operators demands aggregate memory bandwidth exceeding tens of terabytes per second. By coordinating 8,192 GH200 superchips using NVLink and InfiniBand fabrics, JUPITER delivers the aggregate memory capacity and coherent memory interconnects necessary to compute non-Clifford noise trajectories without truncating quantum entanglement witness parameters.
Edited by Romila DSilva, Induportals Editor, with AI assistance.
www.nvidia.com